
Revolut Outage Hits Card Payments and Transfers Worldwide
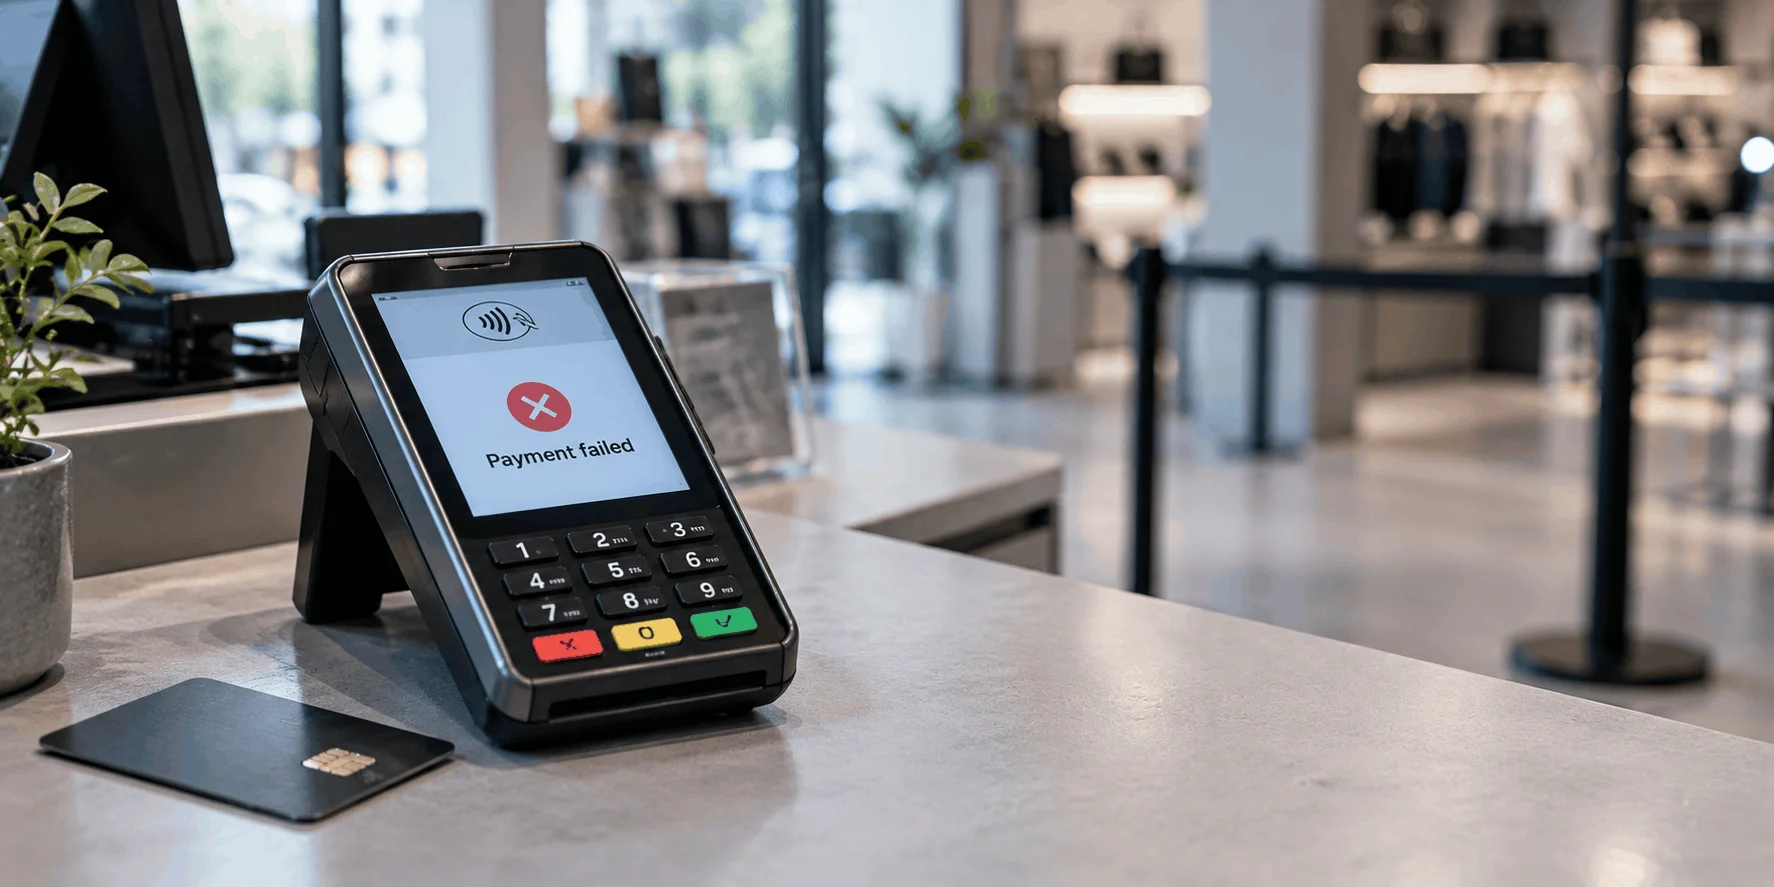
Revolut customers across Europe spent Tuesday morning locked out of their accounts, unable to open the app, move money or pay by card. The Revolut outage started shortly after 06:00 UTC on 20 October and reached most of the company’s product range within the hour. Down detector logged 1,458 reports by 08:00 UK time. Revolut confirmed the disruption and told customers their money and data were safe, though it named no cause.
What Stopped Working
The Revolut outage reached far past the mobile app and into the services customers lean on every day. Sign-ins, card payments, transfers, ATM withdrawals, currency exchange, stock trading and live support chat all failed or degraded. Later snapshots of the status page put the count at 31 services, and business accounts sat in the same queue as personal ones.
Card declines made this Revolut outage harder to route around than most banking failures. When an app goes down, customers can normally still tap a physical card at a till. This time the card failed too, so people found themselves at checkouts with no way to pay.
Revolut’s public statement confirmed a disruption across multiple services and repeated that customer funds and data remained secure. Engineers had been on the problem since it surfaced that morning, but the company released no customer numbers, no root cause and no restoration estimate.
A status page that said everything was fine
For part of the morning, the system status page reported all systems operational while customers could not sign in. Small discrepancies like that cost trust quickly. People who open a status page during an outage want confirmation that someone has noticed.
The Google Cloud Incident Behind the Disruption
Google reported trouble in europe-west2, its London region, beginning at 23:08 US Pacific on 19 October. That converts to 06:08 UTC on Tuesday, minutes before the first customer reports appeared. Google described elevated errors and intermittent network failures across multiple services in the region, and it published no workaround.
The affected products read like an inventory of modern application infrastructure, which explains the breadth of the fallout. Cloud Run, App Engine, Google Kubernetes Engine, Cloud Filestore, NetApp Volumes and the managed Kafka service all took damage. An application that runs its containers, its event pipeline and its storage in one region loses all three the moment that region degrades. Recovery then sits with a provider nobody inside the affected company can escalate to directly.
Revolut has not named Google as the cause of the Revolut outage, and Google’s incident notes name no customers. But the timing matches to the minute, Revolut runs on Google Cloud as a primary provider, and the same window produced failures at a long list of other British brands.
One Region, Many Casualties
Downdetector spikes appeared at the same time for Lloyds Bank, HSBC, Bank of Scotland, Royal Mail, Rightmove, DPD, BT and Screwfix. Lloyds passed roughly 500 reports by 09:27 and acknowledged that other organisations were seeing similar problems. The pattern pointed to shared infrastructure rather than a fault inside any single company, with the Revolut outage the most visible symptom of something larger.
Three banks, a postal operator, a property portal and a courier network all drew on capacity in the same London region. Each runs its own security programme, its own change management and its own resilience testing. None of that mattered once the layer beneath them started returning errors.
Concentration risk of this kind rarely reaches a risk register in a form anyone acts on. A bank can map its own dependencies in detail and still see nothing of how many peers sit in the same failure domain.
Why Zone Redundancy Did Not Contain the Revolut Outage
The europe-west2 region contains three availability zones, which exist so that a hardware or power fault in one does not take down the others. Reports pointed to europe-west2-b as the origin of Tuesday’s problems. Zonal design handles that kind of localised failure well.
Regional networking faults break that model in a way zonal separation was never built to absorb. Once errors and packet loss spread across the shared network fabric, an application distributed across all three zones still sits inside the blast radius. The Revolut outage fits that second category rather than a clean single-zone loss.
Real protection against the failure mode behind the Revolut outage means running in more than one region, and that costs money. Active-active multi-region architecture roughly doubles infrastructure spend and complicates data residency. It also introduces consistency problems that are genuinely hard to solve for payment systems.
Availability Is a Security Problem
Nothing in the Revolut outage touched confidentiality or integrity, and that distinction matters for how the incident gets classified. No data left the building, no attacker gained access, and balances stayed exactly where they were. Availability, the third leg of the security triad, collapsed anyway.
Regulators across Europe treat availability as a supervisory matter in its own right. DORA requires EU financial entities to manage ICT third-party risk and to demonstrate they can keep operating through disruption. UK operational resilience rules set comparable expectations, including a regime aimed at critical third-party providers to the financial sector.
A single cloud region taking several banks offline on one morning is precisely the scenario those rules anticipate. Supervisors will ask which impact tolerances broke, for how long, and what fallback existed while customers stood at tills.
Outages Create a Window for Fraud
News of the Revolut outage travelled fast, and criminals read that kind of news as closely as anyone. Within hours of a major disruption, phishing messages start arriving that promise to restore access, verify an account or release a stuck payment. They work because the recipient already knows something is wrong.
Customers caught in the Revolut outage should treat every unexpected message about it as hostile until proven otherwise. Legitimate updates appear inside the app and on official channels, never through a link in a text message. No bank asks for a passcode, a card number or a one-time code in order to fix a service problem.
After service returns
Customers should go back through their statements once service settles into something stable. Repeated payment attempts during a disruption sometimes post more than once, and genuine duplicate charges give cover to fraudulent ones. Report anything unfamiliar through the app rather than a number found in a search result.
What the Incident Leaves Behind
Indicators tied to the Revolut outage began recovering by mid-morning, with report volumes falling for Revolut, Lloyds, Rightmove and DPD. Neither company has published a root cause analysis, and the full duration of the disruption remains unclear.
The useful question for any business watching the Revolut outage is a blunt one. How many of your critical suppliers sit in the sam ecloud region, and would you know before the errors started? Most organisations can answer for their own stack. Few can answer for their payment processor, their identity provider and their logistics partner at once.
Resilience planning that stops at the company boundary leaves that gap wide open. Map the third-party and fourth-party dependencies, agree degraded-mode procedures and test them against a regional failure. All of that costs far less than finding out live on a Tuesday morning.
Subscribe to receive the latest blog posts to your inbox every week.